

EBOOK
Enterprise AI Agents in 2026: The CTO's Production Readiness Playbook
A practical five-gate framework and 90-day rollout for taking enterprise AI agents from impressive demos to controlled, measurable production systems.
View details
A sales lead arrives at 21:40. The website chatbot answers three product questions, then asks the buyer to wait. Nobody owns after-hours routing. The CRM still stores “new” until a person copies the chat into a note the next morning. The team bought a model. The operating system did not change.
That pattern is AI-added work: a model sits on an old path. AI-native work starts from a different question: which customer job should the system complete, record, review, and stop—before anyone picks a chatbot, an agent, or a vendor.
Copy the diagnostic below onto one workflow. If three or more fields fail, do not scale the bot. Redesign the job first. NIST’s AI Risk Management Framework treats context, oversight, and limits as design inputs, not a slide after go-live.
AI-added teams keep the same owners, fields, and weekly report, then insert generation into one step. The model can draft a reply, summarize a ticket, or score a lead. The rest of the job still depends on memory, chat, and a person who happened to be online.
AI-native teams redesign the job around four operating facts:
This is not a claim that every process should become autonomous. Anthropic’s guidance on effective agents still prefers the simplest controlled workflow that produces a measurable result. AI-native means the workflow is designed for machine participation with human control—not that the machine is unsupervised.
| Signal | AI-added | AI-native |
|---|---|---|
| Starting question | Which tool can we plug in? | Which job must complete overnight? |
| Customer state | Split across chat, inbox, and CRM notes | One record the bot and the person both update |
| Wrong output | Someone notices later, if they notice | A named reviewer, a time limit, and a fallback |
| Success metric | Messages sent or tickets touched | Completed jobs, recovered jobs, and safe stops |
An AI-native team can still use a deterministic form, a scripted chatbot, or a bounded agent. The label describes the operating system, not the model class.
Do not score “the company.” Score one job: new-lead first response, booking confirmation, order-status answer, or unpaid-invoice reminder. Fill every field. A blank is a fail.
| Field | Pass | Fail | Stop if |
|---|---|---|---|
| Job boundary | One outcome, one owner, one exit state | “Improve sales with AI” | The outcome cannot be named in one sentence |
| Customer state | Bot and human read/write the same record | Chat log is the only memory | The next shift cannot reconstruct the case |
| Permitted action | Answer, draft, or execute is explicit | The bot may “help however it can” | Write access exists without a range |
| Review | Sample, exception, or approval is timed | “We glance at chats” | No one can reject or reverse the output |
| Handoff | Accepted, declined, or overdue is stored | A notification equals transfer | The receiving queue has no owner |
| Measurement | Baseline and target use the same unit | Token count or “AI usage” | You cannot tell if the job got faster or safer |
Score each field pass or fail. Three fails means the workflow is AI-added even if the demo looks fluent. Do not average the score across unrelated jobs. A native booking flow does not make an unmanaged discount bot native.
OpenAI’s practical guide to building AI agents puts tools, guardrails, and human intervention on the same design sheet. The diagnostic above is that sheet in operating language: if you cannot name the tool, the limit, and the person, the agent is not ready.
The session should produce a filled table, not a strategy deck. If the table is incomplete after 45 minutes, the job is still too broad. Narrow it until a night-shift operator could complete the row.
Adding a model to an existing path is the right first move when all of these are true:
Examples: drafting a follow-up from a completed discovery note; suggesting a help-center article that already exists; extracting a phone number into a field a human confirms.
Do not treat that as AI-native. Treat it as a safe assist. It can still be valuable. It does not require a new operating model. It also does not fix a broken queue.
Redesign when the model would sit on a path that already loses work:
Those failures are operating failures. A more capable model will repeat them faster. OECD AI Principles put accountability and transparency on the organization, not on the vendor logo. If no person can explain a decision, the system is not ready for customer-facing action.
After the diagnostic, rebuild only the failing loops. Do not start with a multi-agent diagram.
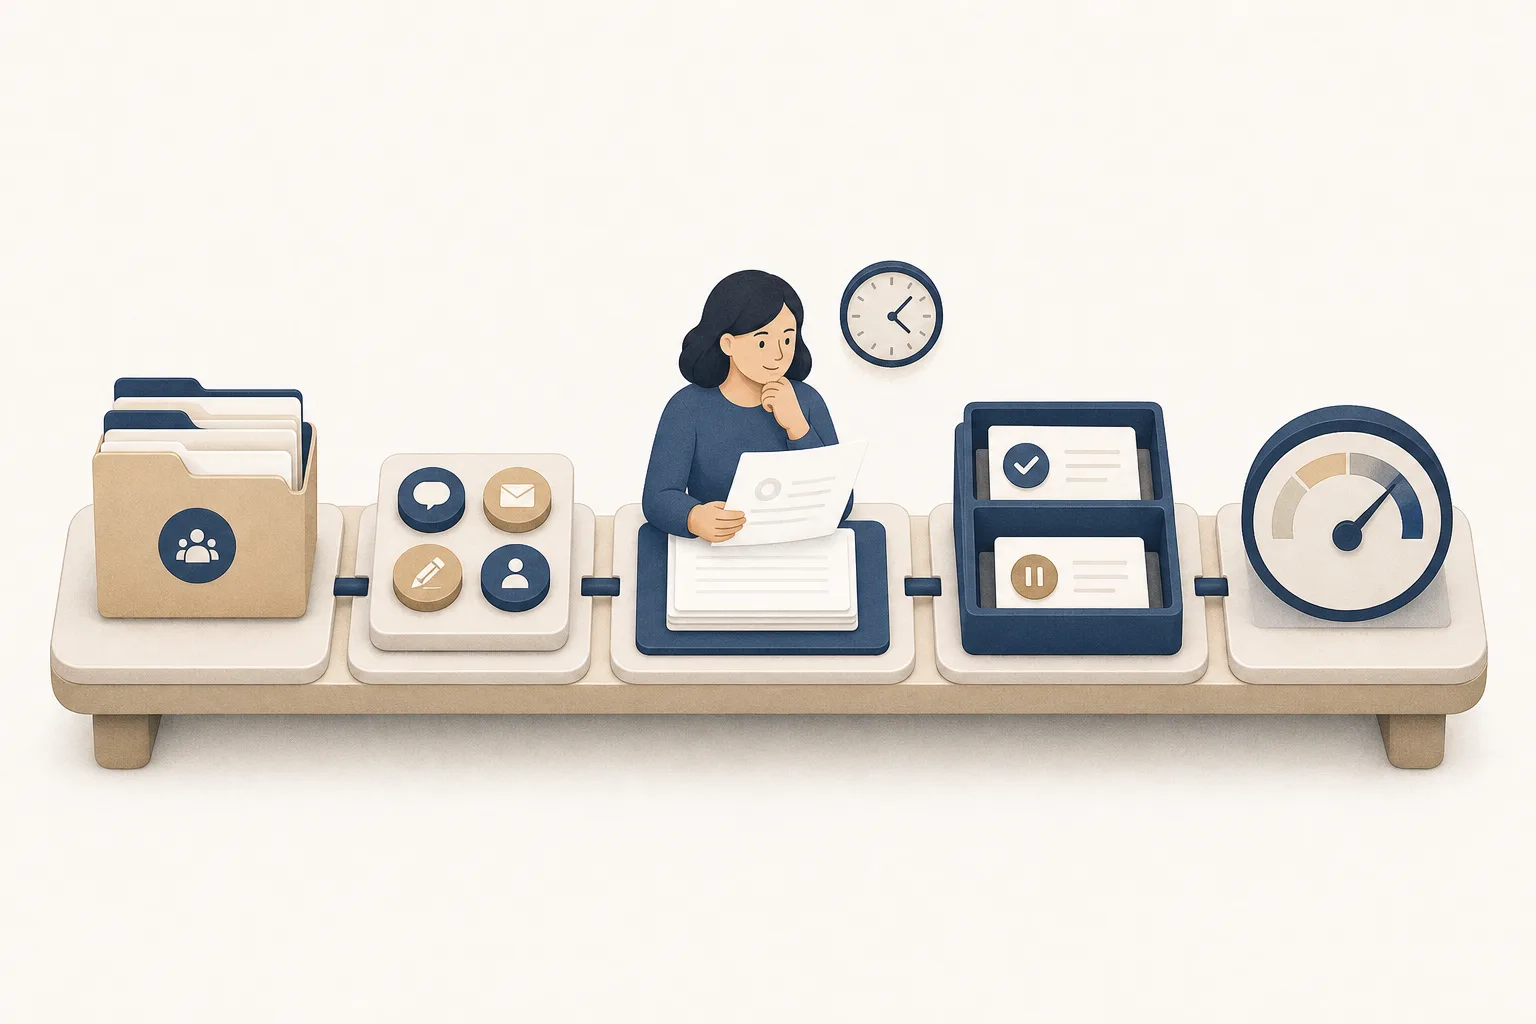
The bot and the human must share one case record. Minimum fields:
If the “record” is a screenshot in a group chat, the workflow cannot be native. Night staff will re-ask questions the afternoon staff already answered.
Write the record so a person who did not see the original chat can continue. That is the test. A summary that omits the promised delivery date, the SKU, or the complaint type is not a record. It is a recap for people who were already in the thread.
When identity is incomplete, store what is known and what is missing. Do not invent a merged profile. A native system is allowed to say “we do not know which order this is” and stop. It is not allowed to guess an order and complete a refund path.
Separate four verbs. Mixing them is how fluent answers become unapproved commitments.
| Verb | Meaning | Typical control |
|---|---|---|
| Answer | Repeat an approved fact | Source page must be current |
| Draft | Propose text for a person | Person must send or edit |
| Route | Choose a queue or owner | Queue must exist and be staffed |
| Execute | Change a system of record | Range, approval, and reversal |
A chatbot that “answers” a custom discount is actually executing a commercial commitment. Rename the verb. Then either forbid it or add approval.
Keep the action list short. Anthropic’s agent guidance is explicit: add autonomy only when a simpler composition fails. If a form plus a rule engine completes the job, do not wrap it in an agent.
Publish the verb list next to the workflow, not inside a prompt. Prompts change. The permitted verbs are an operating policy. If a vendor update silently adds “create coupon,” the policy—not the model card—should reject it.
Review is a job with a clock, not a culture of “being careful.”
Choose one mode per action class:
Write who reviews, within how many minutes or hours, and what happens if the clock expires. An expired review must produce a visible state: held, rolled back, or handed to a person. Silence is not a pass.
NIST’s risk framing is useful here: document the context of use and the human oversight that remains after automation. If oversight is “the founder reads Slack,” it will fail on the first sick day.
Review quality depends on the unit of work. Reviewing “the chatbot” is not possible. Reviewing “20 booking confirmations from Tuesday” is. Store the output, the evidence, the verb, and the reviewer decision on the same case. Otherwise the weekly meeting becomes anecdote.
A notification is not a handoff. A handoff has three stored outcomes:
Include a packet the receiver can act on: customer intent, evidence, last bot action, and the decision still needed. “Please handle this” is not a packet.
If the receiving team can mark overdue and nobody is paged, the loop is decorative. Fix staffing or narrow the bot’s hours. Do not hide the gap behind a 24/7 badge.
Staffed hours belong in the same record as the bot’s permitted verbs. A native after-hours bot can collect the case and hold it. It should not invent a promise the morning team cannot keep. Write the hold message in the same language as the public FAQ. If the FAQ says “replies within one business day,” the bot may not say “someone is on it now.”
Measure the job in the unit the customer already feels:
Tokens, “AI conversations,” and thumbs-up on a widget can be secondary. They do not tell you whether revenue work completed.
Take a baseline before the model changes the path. If last month’s time-to-response is unknown, the first native act is to count, not to generate.
Unsafe stops are a health metric. A system that never refuses is not confident. It is unconstrained. Track refusals by reason: missing identity, stale policy, out-of-hours execute, or unapproved verb. Those reasons are the backlog for data, staffing, or policy work.
A 16-person product company sells a paid plan. Website leads arrive through a form and a chat widget. Today, whoever sees the widget replies. Nights and weekends wait until morning. The CRM status stays “new” until a person types a note.
| Field | Score | Evidence |
|---|---|---|
| Job boundary | Pass | Outcome: first qualified response or a recorded hold before the next staffed hour |
| Customer state | Fail | Chat and form live in two inboxes; CRM is updated later |
| Permitted action | Fail | Widget can quote unofficial discounts from old chats |
| Review | Fail | No sample; founder sometimes reads threads |
| Handoff | Fail | Sales gets a chat ping; no accept/decline |
| Measurement | Fail | No baseline for time to first response |
Five fails. The team does not need a larger model. It needs one case record and a narrower bot.
This is a worked operating example, not a customer case study and not an Easy AI product result.
The numbers above are a template a team can replace with its own log. They are not a benchmark. If your log is empty, fill the template with last week’s actual timestamps before changing the bot.
What changed was not “more AI.” The widget still talks. The operating system now has a record, a forbidden verb, a clock, and a morning owner.
Keep scope to one job. Expanding to “all customer AI” in month one recreates AI-added chaos with more surfaces.
Success looks like a spreadsheet or CRM view a night operator can use without asking “what happened in chat?”
Success looks like overdue cases that someone is paid to clear.
Widen only if:
If those are false, spend the next 30 days on the same job. A second bot will inherit the same missing record.
Buying a brain for a missing spine. The model cannot store ownership. Your CRM or ticket system must.
Letting the prompt be the policy. Policies belong in a dated page, a permission matrix, and a review rule. Prompts should retrieve them, not author them.
Counting activity as outcomes. A 40% increase in bot messages can hide a 40% increase in confused buyers.
Staffing the demo, not the queue. If sales accepts handoffs only during the vendor workshop, production will fail on Tuesday afternoon.
Copying another company’s architecture. A native bank workflow is not a native six-person shop workflow. Copy the diagnostic, not the diagram.
Calling a refusal a failure. If the bot stops because evidence is missing, that is control. Train the team to complete the record, not to jailbreak the stop.
Translating the English playbook and shipping it. Vietnamese buyers, Zalo hours, invoicing practice, and who can approve a discount may differ from a US funnel. Research the job in the market where the customer waits.
This guide does not certify a company as AI-native, rank vendors, or estimate ROI. It does not claim that autonomous agents outperform scripted chatbots. It does not describe Easy AI product features, prices, or customer results.
Legal, privacy, credit, health, and employment decisions need specialist review beyond this diagnostic. If the workflow can change money, access, or legal status, treat execute as forbidden until that review exists.
The diagnostic is a recommendation for operating design. Teams should replace the worked-example numbers with their own logs. Do not publish those internal numbers as market facts.
Pick the workflow that already breaks overnight. Fill the six fields with someone who takes the handoff, not only with someone who bought the tool. Repair the first failing loop—usually the case record or the forbidden verb—before you add another model.
If you need a definition: AI-native means the job can complete, be reviewed, and stop safely when people are offline, because the record and the controls were designed for that. The model is a participant in that job. It is not the job.
A practical five-gate framework and 90-day rollout for taking enterprise AI agents from impressive demos to controlled, measurable production systems.
View details
A practical guide to designing an AI chatbot that understands needs, qualifies prospects, and hands useful context to the sales team.
View details